Protocol & Evidence Boundary (2026-10-22, RTX 3060 8 GiB): FP16 compute, batch 1, 128 prompt tokens, 50 greedy output tokens, 2 warm-ups, 3 measured runs, 32 zero-shot examples per task (smoke evaluation). Legacy simulated outputs are separated from measured hardware metrics.
| Model | Weights / Attention | Prefill (tok/s) | Decode (tok/s) | Peak CUDA (MiB) | ARC (32 ex) | HellaSwag | PIQA |
|---|
Highlight: 0.5B GPTQ Int4 / SDPA cut peak CUDA allocation by 52.81% relative to FP16 / SDPA (961 → 454 MiB), while 7B GPTQ Int4 / SDPA reached 1,414.05 prefill tok/s and 27.36 decode tok/s inside 8 GiB VRAM.
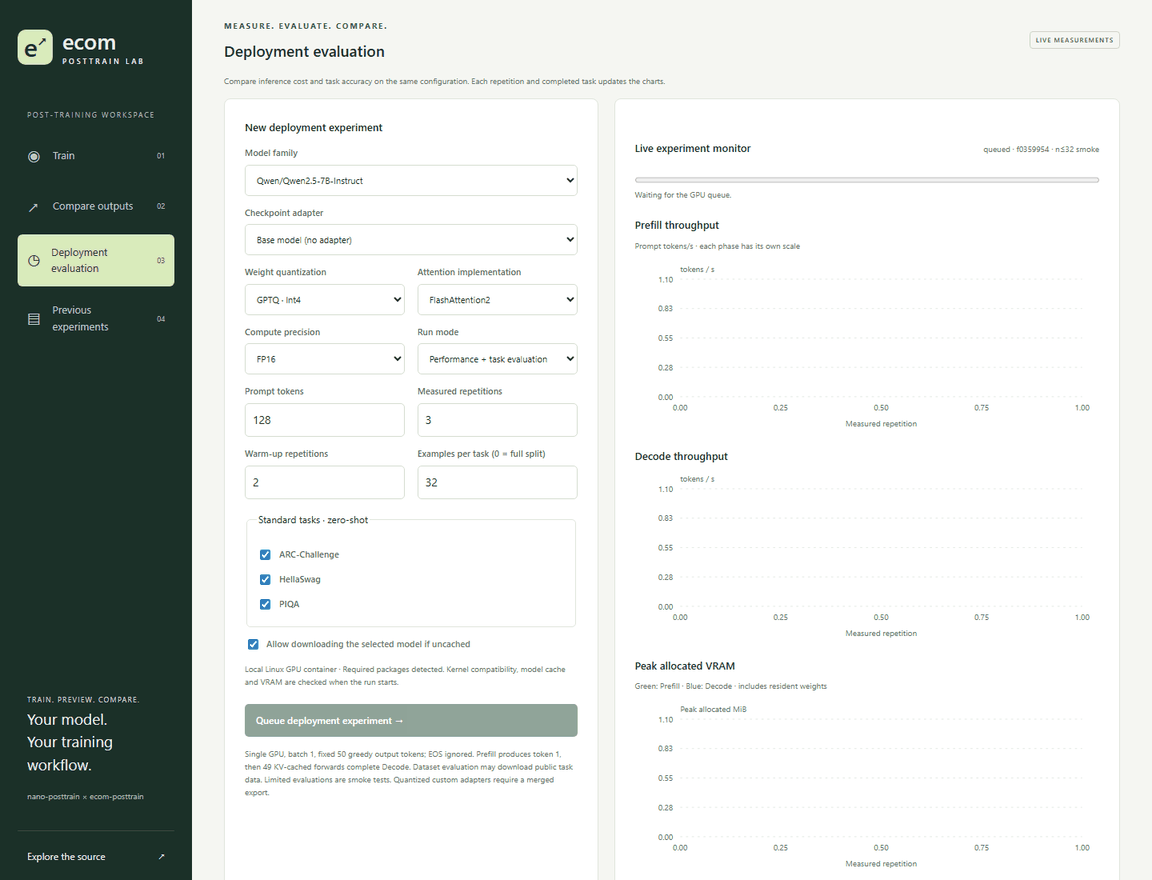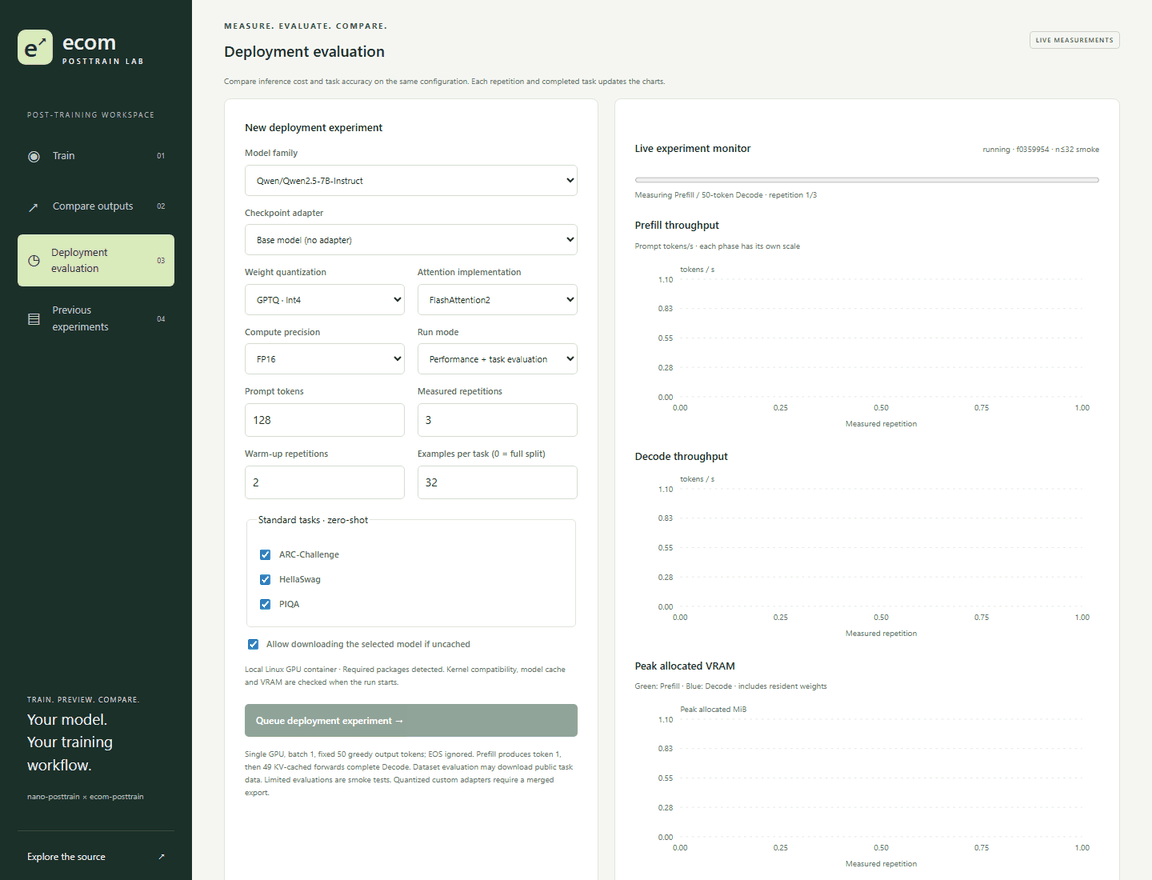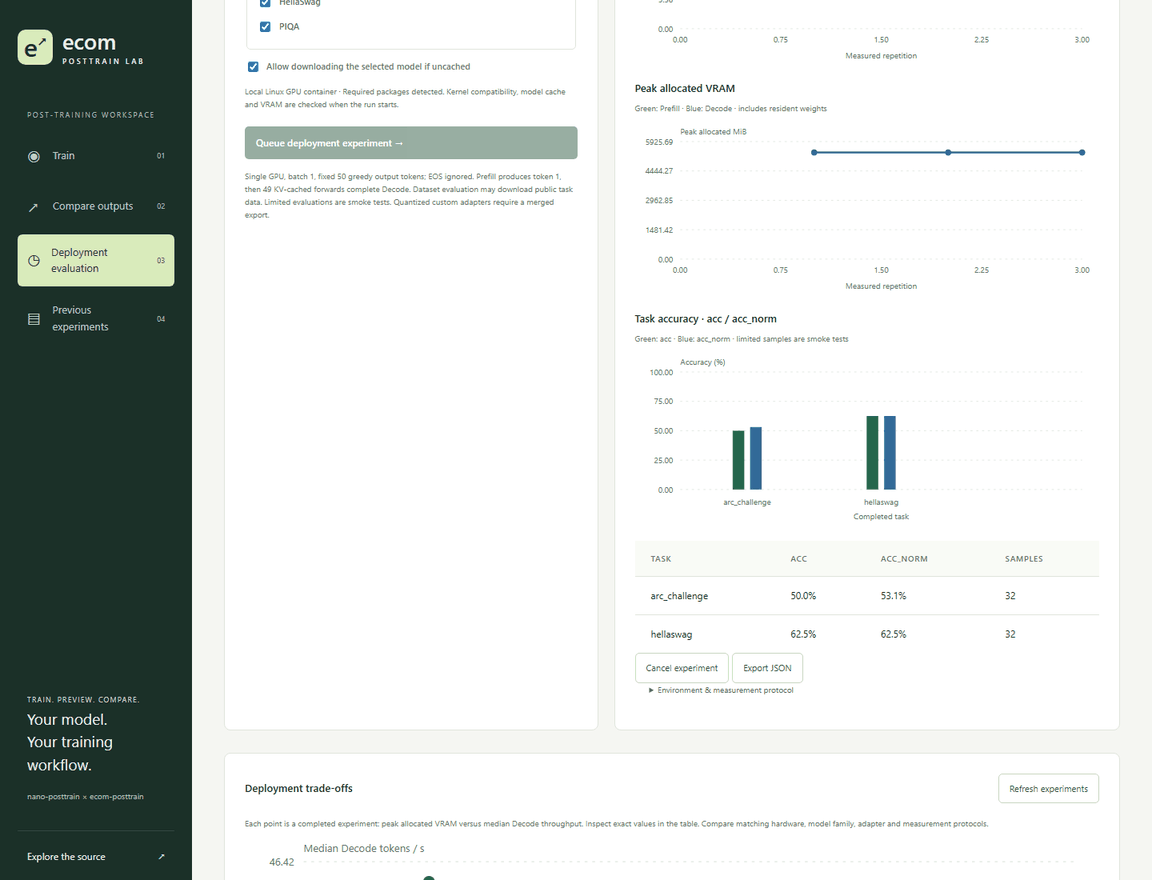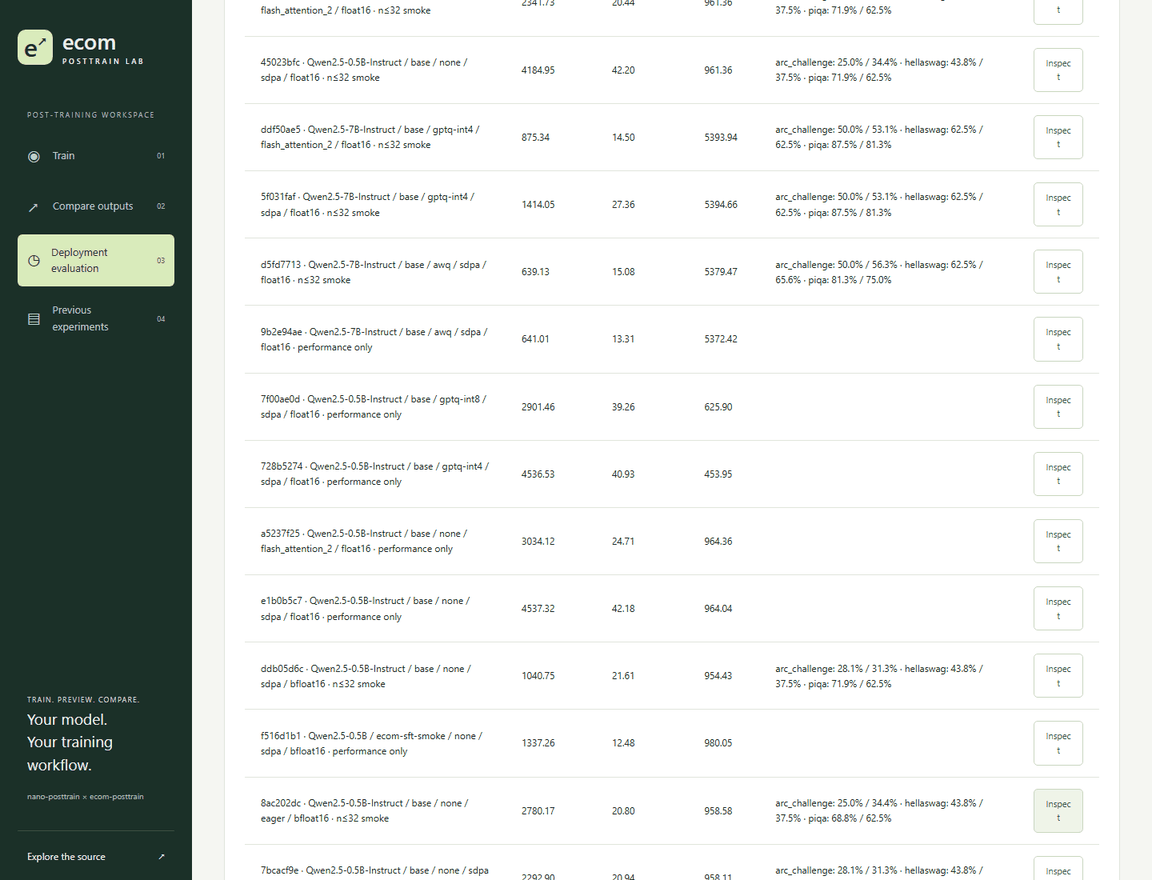
Local RTX 3060 (8 GiB) workflow recording: 7B GPTQ Int4, FlashAttention2, live throughput & accuracy